
See also
This tutorial is the source of truth for the isaaclab-randomizing-with-events agent skill
(skills/user/domain-randomization-events/).
When you change this page, update the skill so agent guidance stays in sync. See
Agent Skills.
Creating a Direct Workflow RL Environment#
In addition to the envs.ManagerBasedRLEnv class, which encourages the use of configuration classes
for more modular environments, the DirectRLEnv class allows for more direct control
in the scripting of environment.
Instead of using Manager classes for defining rewards and observations, the direct workflow tasks implement the full reward and observation functions directly in the task script. This allows for more control in the implementation of the methods, such as using pytorch jit features, and provides a less abstracted framework that makes it easier to find the various pieces of code.
In this tutorial, we will configure the cartpole environment using the direct workflow implementation to create a task for balancing the pole upright. We will declare its scene and implement actions, resets, rewards, and observations.
The Code#
For this tutorial, we use the cartpole environment defined in isaaclab_tasks.core.cartpole module.
Code for cartpole_direct_env.py
  1# Copyright (c) 2022-2026, The Isaac Lab Project Developers (https://github.com/isaac-sim/IsaacLab/blob/main/CONTRIBUTORS.md).
  2# All rights reserved.
  3#
  4# SPDX-License-Identifier: BSD-3-Clause
  5
  6from __future__ import annotations
  7
  8from collections.abc import Sequence
  9from typing import TYPE_CHECKING
 10
 11import torch
 12
 13from isaaclab.envs import DirectRLEnv
 14from isaaclab.utils.math import sample_uniform, wrap_to_pi
 15
 16if TYPE_CHECKING:
 17    from isaaclab_tasks.core.cartpole.cartpole_direct_env_cfg import CartpoleEnvCfg
 18
 19
 20class CartpoleEnv(DirectRLEnv):
 21    """Cartpole balancing environment driven by proprioceptive (joint-state) observations."""
 22
 23    cfg: CartpoleEnvCfg
 24
 25    def __init__(self, cfg: CartpoleEnvCfg, render_mode: str | None = None, **kwargs):
 26        super().__init__(cfg, render_mode, **kwargs)
 27
 28        self.cartpole = self.scene["cartpole"]
 29        self._cart_dof_idx, _ = self.cartpole.find_joints(self.cfg.cart_dof_name)
 30        self._pole_dof_idx, _ = self.cartpole.find_joints(self.cfg.pole_dof_name)
 31        self.action_scale = self.cfg.action_scale
 32
 33        self.joint_pos = self.cartpole.data.joint_pos.torch
 34        self.joint_vel = self.cartpole.data.joint_vel.torch
 35
 36    def _pre_physics_step(self, actions: torch.Tensor) -> None:
 37        self.actions = self.action_scale * actions.clone()
 38
 39    def _apply_action(self) -> None:
 40        self.cartpole.set_joint_effort_target_index(target=self.actions, joint_ids=self._cart_dof_idx)
 41
 42    def _get_observations(self) -> dict:
 43        joint_pos_rel = self.joint_pos - self.cartpole.data.default_joint_pos.torch
 44        joint_vel_rel = self.joint_vel - self.cartpole.data.default_joint_vel.torch
 45        obs = torch.cat(
 46            (
 47                joint_pos_rel[:, self._cart_dof_idx[0]].unsqueeze(dim=1),
 48                joint_pos_rel[:, self._pole_dof_idx[0]].unsqueeze(dim=1),
 49                joint_vel_rel[:, self._cart_dof_idx[0]].unsqueeze(dim=1),
 50                joint_vel_rel[:, self._pole_dof_idx[0]].unsqueeze(dim=1),
 51            ),
 52            dim=-1,
 53        )
 54        observations = {"policy": obs}
 55        return observations
 56
 57    def _get_rewards(self) -> torch.Tensor:
 58        total_reward = compute_rewards(
 59            self.cfg.rew_scale_alive,
 60            self.cfg.rew_scale_terminated,
 61            self.cfg.rew_scale_pole_pos,
 62            self.cfg.rew_scale_cart_vel,
 63            self.cfg.rew_scale_pole_vel,
 64            self.joint_pos[:, self._pole_dof_idx[0]],
 65            self.joint_vel[:, self._pole_dof_idx[0]],
 66            self.joint_vel[:, self._cart_dof_idx[0]],
 67            self.reset_terminated,
 68            self.step_dt,
 69        )
 70        return total_reward
 71
 72    def _get_dones(self) -> tuple[torch.Tensor, torch.Tensor]:
 73        self.joint_pos = self.cartpole.data.joint_pos.torch
 74        self.joint_vel = self.cartpole.data.joint_vel.torch
 75
 76        time_out = self.episode_length_buf >= self.max_episode_length
 77        out_of_bounds = torch.any(torch.abs(self.joint_pos[:, self._cart_dof_idx]) > self.cfg.max_cart_pos, dim=1)
 78        return out_of_bounds, time_out
 79
 80    def _reset_idx(self, env_ids: Sequence[int] | None):
 81        if env_ids is None:
 82            env_ids = self.cartpole._ALL_INDICES
 83
 84        # Log survival success rate before resetting
 85        survived = self.reset_time_outs[env_ids].float()
 86        self.extras.setdefault("log", {})["Metrics/success_rate"] = survived.mean().item()
 87
 88        super()._reset_idx(env_ids)
 89
 90        joint_pos = self.cartpole.data.default_joint_pos.torch[env_ids].clone()
 91        joint_pos[:, self._cart_dof_idx] += sample_uniform(
 92            self.cfg.initial_cart_position_range[0],
 93            self.cfg.initial_cart_position_range[1],
 94            joint_pos[:, self._cart_dof_idx].shape,
 95            joint_pos.device,
 96        )
 97        joint_vel = self.cartpole.data.default_joint_vel.torch[env_ids].clone()
 98        joint_vel[:, self._cart_dof_idx] += sample_uniform(
 99            self.cfg.initial_cart_velocity_range[0],
100            self.cfg.initial_cart_velocity_range[1],
101            joint_vel[:, self._cart_dof_idx].shape,
102            joint_vel.device,
103        )
104        joint_pos[:, self._pole_dof_idx] += sample_uniform(
105            self.cfg.initial_pole_angle_range[0],
106            self.cfg.initial_pole_angle_range[1],
107            joint_pos[:, self._pole_dof_idx].shape,
108            joint_pos.device,
109        )
110        joint_vel[:, self._pole_dof_idx] += sample_uniform(
111            self.cfg.initial_pole_velocity_range[0],
112            self.cfg.initial_pole_velocity_range[1],
113            joint_vel[:, self._pole_dof_idx].shape,
114            joint_vel.device,
115        )
116
117        # clamp the sampled state to the joint limits (matches the manager-based reset_joints_by_offset)
118        joint_pos_limits = self.cartpole.data.soft_joint_pos_limits.torch[env_ids]
119        joint_pos = joint_pos.clamp_(joint_pos_limits[..., 0], joint_pos_limits[..., 1])
120        joint_vel_limits = self.cartpole.data.soft_joint_vel_limits.torch[env_ids]
121        joint_vel = joint_vel.clamp_(-joint_vel_limits, joint_vel_limits)
122
123        default_root_pose = self.cartpole.data.default_root_pose.torch[env_ids].clone()
124        default_root_pose[:, :3] += self.scene.env_origins[env_ids]
125        default_root_vel = self.cartpole.data.default_root_vel.torch[env_ids].clone()
126
127        self.joint_pos[env_ids] = joint_pos
128        self.joint_vel[env_ids] = joint_vel
129
130        self.cartpole.write_root_pose_to_sim_index(root_pose=default_root_pose, env_ids=env_ids)
131        self.cartpole.write_root_velocity_to_sim_index(root_velocity=default_root_vel, env_ids=env_ids)
132        self.cartpole.write_joint_position_to_sim_index(position=joint_pos, env_ids=env_ids)
133        self.cartpole.write_joint_velocity_to_sim_index(velocity=joint_vel, env_ids=env_ids)
134
135
136@torch.jit.script
137def compute_rewards(
138    rew_scale_alive: float,
139    rew_scale_terminated: float,
140    rew_scale_pole_pos: float,
141    rew_scale_cart_vel: float,
142    rew_scale_pole_vel: float,
143    pole_pos: torch.Tensor,
144    pole_vel: torch.Tensor,
145    cart_vel: torch.Tensor,
146    reset_terminated: torch.Tensor,
147    step_dt: float,
148):
149    pole_pos = wrap_to_pi(pole_pos)
150    rew_alive = rew_scale_alive * (1.0 - reset_terminated.float())
151    rew_termination = rew_scale_terminated * reset_terminated.float()
152    rew_pole_pos = rew_scale_pole_pos * torch.sum(torch.square(pole_pos).unsqueeze(dim=1), dim=-1)
153    rew_cart_vel = rew_scale_cart_vel * torch.sum(torch.abs(cart_vel).unsqueeze(dim=1), dim=-1)
154    rew_pole_vel = rew_scale_pole_vel * torch.sum(torch.abs(pole_vel).unsqueeze(dim=1), dim=-1)
155    total_reward = (rew_alive + rew_termination + rew_pole_pos + rew_cart_vel + rew_pole_vel) * step_dt
156    return total_reward
The Code Explained#
Similar to the manager-based environments, a configuration class is defined for the task to hold settings
for the simulation parameters, the scene, the actors, and the task. With the direct workflow implementation,
the envs.DirectRLEnvCfg class is used as the base class for configurations.
Since the direct workflow implementation does not use Action and Observation managers, the task
config should define the number of actions and observations for the environment.
@configclass
class CartpoleEnvCfg(DirectRLEnvCfg):
   ...
   action_space = 1
   observation_space = 4
   state_space = 0
The config class can also be used to define task-specific attributes, such as scaling for reward terms and thresholds for reset conditions.
@configclass
class CartpoleEnvCfg(DirectRLEnvCfg):
   ...
   # reset
   max_cart_pos = 3.0
   initial_pole_angle_range = [-0.25, 0.25]

   # reward scales
   rew_scale_alive = 1.0
   rew_scale_terminated = -2.0
   rew_scale_pole_pos = -1.0
   rew_scale_cart_vel = -0.01
   rew_scale_pole_vel = -0.005
When creating a new environment, the code should define a new class that inherits from DirectRLEnv.
class CartpoleEnv(DirectRLEnv):
   cfg: CartpoleEnvCfg

   def __init__(self, cfg: CartpoleEnvCfg, render_mode: str | None = None, **kwargs):
     super().__init__(cfg, render_mode, **kwargs)
The class can also hold class variables that are accessible by all functions in the class, including functions for applying actions, computing resets, rewards, and observations.
Scene Creation#
Direct and manager-based environments use the same declarative scene lifecycle. Define the
assets and sensors on an InteractiveSceneCfg subclass:
@configclass
class CartpoleSceneCfg(InteractiveSceneCfg):
    """Cartpole assets constructed and cloned as one scene."""

    ground = AssetBaseCfg(prim_path="/World/ground", spawn=sim_utils.GroundPlaneCfg())
    cartpole: ArticulationCfg = CARTPOLE_CFG.replace(prim_path="{ENV_REGEX_NS}/Robot")
    light = AssetBaseCfg(
        prim_path="/World/Light",
        spawn=sim_utils.DistantLightCfg(intensity=2000.0),
        init_state=AssetBaseCfg.InitialStateCfg(
            rot=(-0.14644663035869598, -0.3535534143447876, -0.3535534143447876, 0.8535533547401428)
        ),
    )
Assign that configuration to the task’s scene field. DirectRLEnv
constructs the scene and completes its one clone lifecycle before the task constructor resumes.
Task code can then keep a convenient reference to a declared entity:
self.cartpole = self.scene["cartpole"]
Defining Rewards#
Reward function should be defined in the _get_rewards(self) API, which returns the reward
buffer as a return value. Within this function, the task is free to implement the logic of
the reward function. In this example, we implement a Pytorch JIT function that computes
the various components of the reward function.
def _get_rewards(self) -> torch.Tensor:
     total_reward = compute_rewards(
         self.cfg.rew_scale_alive,
         self.cfg.rew_scale_terminated,
         self.cfg.rew_scale_pole_pos,
         self.cfg.rew_scale_cart_vel,
         self.cfg.rew_scale_pole_vel,
         self.joint_pos[:, self._pole_dof_idx[0]],
         self.joint_vel[:, self._pole_dof_idx[0]],
         self.joint_pos[:, self._cart_dof_idx[0]],
         self.joint_vel[:, self._cart_dof_idx[0]],
         self.reset_terminated,
     )
     return total_reward

@torch.jit.script
def compute_rewards(
    rew_scale_alive: float,
    rew_scale_terminated: float,
    rew_scale_pole_pos: float,
    rew_scale_cart_vel: float,
    rew_scale_pole_vel: float,
    pole_pos: torch.Tensor,
    pole_vel: torch.Tensor,
    cart_pos: torch.Tensor,
    cart_vel: torch.Tensor,
    reset_terminated: torch.Tensor,
):
    rew_alive = rew_scale_alive * (1.0 - reset_terminated.float())
    rew_termination = rew_scale_terminated * reset_terminated.float()
    rew_pole_pos = rew_scale_pole_pos * torch.sum(torch.square(pole_pos), dim=-1)
    rew_cart_vel = rew_scale_cart_vel * torch.sum(torch.abs(cart_vel), dim=-1)
    rew_pole_vel = rew_scale_pole_vel * torch.sum(torch.abs(pole_vel), dim=-1)
    total_reward = rew_alive + rew_termination + rew_pole_pos + rew_cart_vel + rew_pole_vel
    return total_reward
Defining Observations#
The observation buffer should be computed in the _get_observations(self) function,
which constructs the observation buffer for the environment. At the end of this API,
a dictionary should be returned that contains policy as the key, and the full
observation buffer as the value. For asymmetric policies, the dictionary should also
include the key critic and the states buffer as the value.
    def _get_observations(self) -> dict:
        joint_pos_rel = self.joint_pos - self.cartpole.data.default_joint_pos.torch
        joint_vel_rel = self.joint_vel - self.cartpole.data.default_joint_vel.torch
        obs = torch.cat(
            (
                joint_pos_rel[:, self._cart_dof_idx[0]].unsqueeze(dim=1),
                joint_pos_rel[:, self._pole_dof_idx[0]].unsqueeze(dim=1),
                joint_vel_rel[:, self._cart_dof_idx[0]].unsqueeze(dim=1),
                joint_vel_rel[:, self._pole_dof_idx[0]].unsqueeze(dim=1),
            ),
            dim=-1,
        )
        observations = {"policy": obs}
        return observations
Computing Dones and Performing Resets#
Populating the dones buffer should be done in the _get_dones(self) method.
This method is free to implement logic that computes which environments would need to be reset
and which environments have reached the episode length limit. Both results should be
returned by the _get_dones(self) function, in the form of a tuple of boolean tensors.
    def _get_dones(self) -> tuple[torch.Tensor, torch.Tensor]:
        self.joint_pos = self.cartpole.data.joint_pos.torch
        self.joint_vel = self.cartpole.data.joint_vel.torch

        time_out = self.episode_length_buf >= self.max_episode_length
        out_of_bounds = torch.any(torch.abs(self.joint_pos[:, self._cart_dof_idx]) > self.cfg.max_cart_pos, dim=1)
        return out_of_bounds, time_out
Once the indices for environments requiring reset have been computed, the _reset_idx(self, env_ids)
function performs the reset operations on those environments. Within this function, new states
for the environments requiring reset should be set directly into simulation.
    def _reset_idx(self, env_ids: Sequence[int] | None):
        if env_ids is None:
            env_ids = self.cartpole._ALL_INDICES

        # Log survival success rate before resetting
        survived = self.reset_time_outs[env_ids].float()
        self.extras.setdefault("log", {})["Metrics/success_rate"] = survived.mean().item()

        super()._reset_idx(env_ids)

        joint_pos = self.cartpole.data.default_joint_pos.torch[env_ids].clone()
        joint_pos[:, self._cart_dof_idx] += sample_uniform(
            self.cfg.initial_cart_position_range[0],
            self.cfg.initial_cart_position_range[1],
            joint_pos[:, self._cart_dof_idx].shape,
            joint_pos.device,
        )
        joint_vel = self.cartpole.data.default_joint_vel.torch[env_ids].clone()
        joint_vel[:, self._cart_dof_idx] += sample_uniform(
            self.cfg.initial_cart_velocity_range[0],
            self.cfg.initial_cart_velocity_range[1],
            joint_vel[:, self._cart_dof_idx].shape,
            joint_vel.device,
        )
        joint_pos[:, self._pole_dof_idx] += sample_uniform(
            self.cfg.initial_pole_angle_range[0],
            self.cfg.initial_pole_angle_range[1],
            joint_pos[:, self._pole_dof_idx].shape,
            joint_pos.device,
        )
        joint_vel[:, self._pole_dof_idx] += sample_uniform(
            self.cfg.initial_pole_velocity_range[0],
            self.cfg.initial_pole_velocity_range[1],
            joint_vel[:, self._pole_dof_idx].shape,
            joint_vel.device,
        )

        # clamp the sampled state to the joint limits (matches the manager-based reset_joints_by_offset)
        joint_pos_limits = self.cartpole.data.soft_joint_pos_limits.torch[env_ids]
        joint_pos = joint_pos.clamp_(joint_pos_limits[..., 0], joint_pos_limits[..., 1])
        joint_vel_limits = self.cartpole.data.soft_joint_vel_limits.torch[env_ids]
        joint_vel = joint_vel.clamp_(-joint_vel_limits, joint_vel_limits)

        default_root_pose = self.cartpole.data.default_root_pose.torch[env_ids].clone()
        default_root_pose[:, :3] += self.scene.env_origins[env_ids]
        default_root_vel = self.cartpole.data.default_root_vel.torch[env_ids].clone()

        self.joint_pos[env_ids] = joint_pos
        self.joint_vel[env_ids] = joint_vel

        self.cartpole.write_root_pose_to_sim_index(root_pose=default_root_pose, env_ids=env_ids)
        self.cartpole.write_root_velocity_to_sim_index(root_velocity=default_root_vel, env_ids=env_ids)
        self.cartpole.write_joint_position_to_sim_index(position=joint_pos, env_ids=env_ids)
        self.cartpole.write_joint_velocity_to_sim_index(velocity=joint_vel, env_ids=env_ids)
Applying Actions#
There are two APIs that are designed for working with actions. The _pre_physics_step(self, actions) takes in actions
from the policy as an argument and is called once per RL step, prior to taking any physics steps. This function can
be used to process the actions buffer from the policy and cache the data in a class variable for the environment.
    def _pre_physics_step(self, actions: torch.Tensor) -> None:
        self.actions = self.action_scale * actions.clone()
The _apply_action(self) API is called decimation number of times for each RL step, prior to taking
each physics step. This provides more flexibility for environments where actions should be applied
for each physics step.
    def _apply_action(self) -> None:
        self.cartpole.set_joint_effort_target_index(target=self.actions, joint_ids=self._cart_dof_idx)
The Code Execution#
To run training for the direct workflow Cartpole environment, we can use the following command:
uv run --extra rl-games isaaclab train --rl_library rl_games --task=Isaac-Cartpole-Direct
./isaaclab.sh train --rl_library rl_games --task=Isaac-Cartpole-Direct
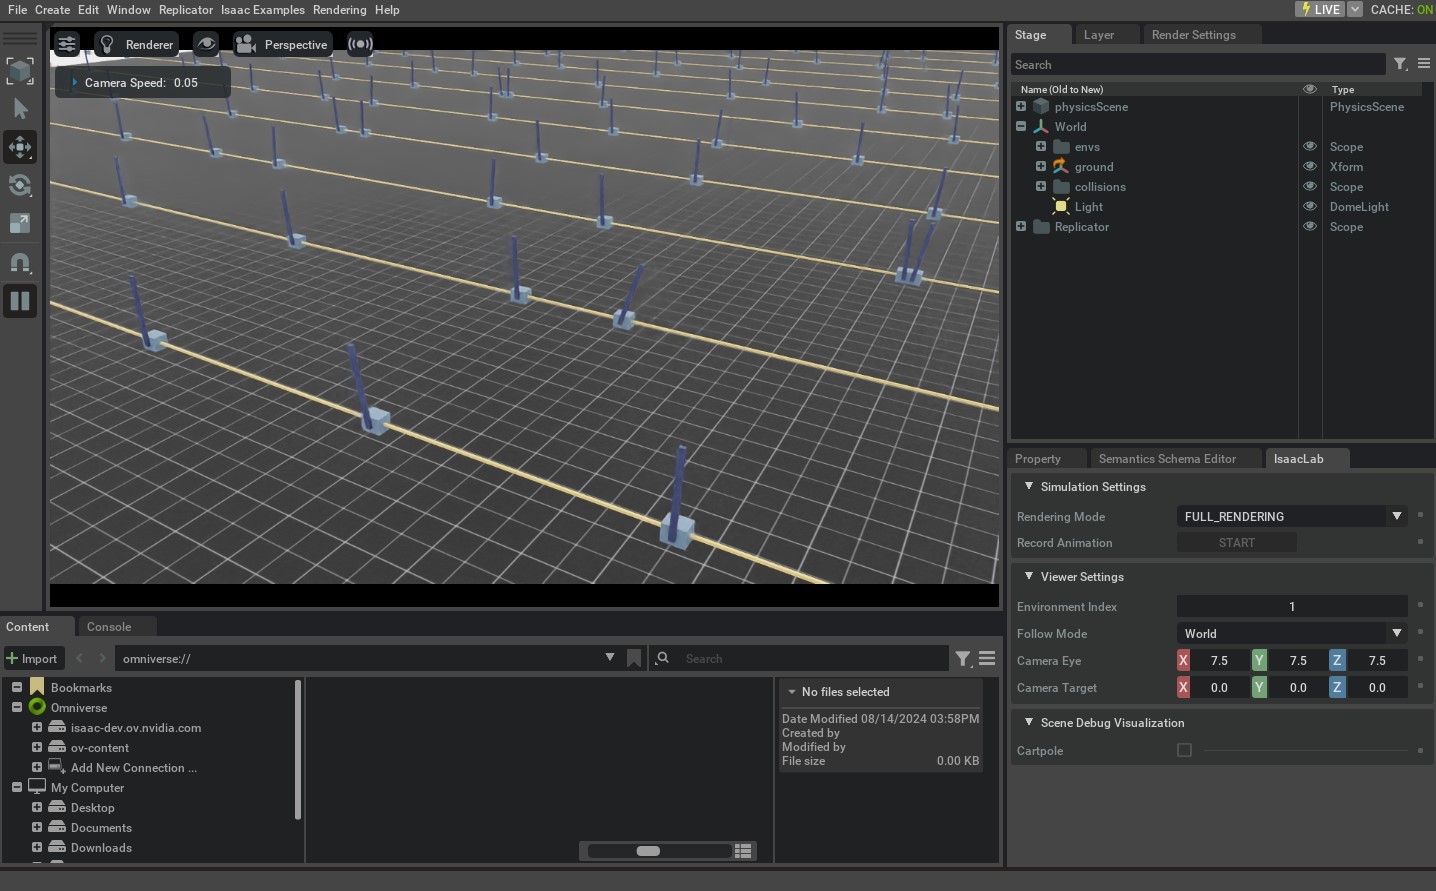
All direct workflow tasks have the suffix -Direct added to the task name to differentiate the implementation style.
Domain Randomization#
In the direct workflow, domain randomization configuration uses the configclass module
to specify a configuration class consisting of EventTermCfg variables.
Below is an example of a configuration class for domain randomization:
@configclass
class EventCfg:
  robot_physics_material = EventTerm(
      func=mdp.randomize_rigid_body_material,
      mode="reset",
      params={
          "asset_cfg": SceneEntityCfg("robot", body_names=".*"),
          "static_friction_range": (0.7, 1.3),
          "dynamic_friction_range": (1.0, 1.0),
          "restitution_range": (1.0, 1.0),
          "num_buckets": 250,
      },
  )
  robot_joint_stiffness_and_damping = EventTerm(
      func=mdp.randomize_actuator_gains,
      mode="reset",
      params={
          "asset_cfg": SceneEntityCfg("robot", joint_names=".*"),
          "stiffness_distribution_params": (0.75, 1.5),
          "damping_distribution_params": (0.3, 3.0),
          "operation": "scale",
          "distribution": "log_uniform",
      },
  )
  reset_gravity = EventTerm(
      func=mdp.randomize_physics_scene_gravity,
      mode="interval",
      is_global_time=True,
      interval_range_s=(36.0, 36.0),  # time_s = num_steps * (decimation * dt)
      params={
          "gravity_distribution_params": ([0.0, 0.0, 0.0], [0.0, 0.0, 0.4]),
          "operation": "add",
          "distribution": "gaussian",
      },
  )
Each EventTerm object is of the EventTermCfg class and takes in a func parameter
for specifying the function to call during randomization, a mode parameter, which can be startup,
reset or interval. THe params dictionary should provide the necessary arguments to the
function that is specified in the func parameter.
Functions specified as func for the EventTerm can be found in the events module.
Note that as part of the "asset_cfg": SceneEntityCfg("robot", body_names=".*") parameter, the name of
the actor "robot" is provided, along with the body or joint names specified as a regex expression,
which will be the actors and bodies/joints that will have randomization applied.
Once the configclass for the randomization terms have been set up, the class must be added
to the base config class for the task and be assigned to the variable events.
@configclass
class MyTaskConfig:
  events: EventCfg = EventCfg()
Action and Observation Noise#
Actions and observation noise can also be added using the configclass module.
Action and observation noise configs must be added to the main task config using the
action_noise_model and observation_noise_model variables:
@configclass
class MyTaskConfig:

    # at every time-step add gaussian noise + bias. The bias is a gaussian sampled at reset
    action_noise_model: NoiseModelWithAdditiveBiasCfg = NoiseModelWithAdditiveBiasCfg(
      noise_cfg=GaussianNoiseCfg(mean=0.0, std=0.05, operation="add"),
      bias_noise_cfg=GaussianNoiseCfg(mean=0.0, std=0.015, operation="abs"),
    )

    # at every time-step add gaussian noise + bias. The bias is a gaussian sampled at reset
    observation_noise_model: NoiseModelWithAdditiveBiasCfg = NoiseModelWithAdditiveBiasCfg(
      noise_cfg=GaussianNoiseCfg(mean=0.0, std=0.002, operation="add"),
      bias_noise_cfg=GaussianNoiseCfg(mean=0.0, std=0.0001, operation="abs"),
    )
NoiseModelWithAdditiveBiasCfg can be used to sample both uncorrelated noise
per step as well as correlated noise that is re-sampled at reset time.
The noise_cfg term specifies the Gaussian distribution that will be sampled at each
step for all environments. This noise will be added to the corresponding actions and
observations buffers at every step.
The bias_noise_cfg term specifies the Gaussian distribution for the correlated noise
that will be sampled at reset time for the environments being reset. The same noise
will be applied each step for the remaining of the episode for the environments and
resampled at the next reset.
If only per-step noise is desired, GaussianNoiseCfg can be used
to specify an additive Gaussian distribution that adds the sampled noise to the input buffer.
@configclass
class MyTaskConfig:
  action_noise_model: GaussianNoiseCfg = GaussianNoiseCfg(mean=0.0, std=0.05, operation="add")
In this tutorial, we learnt how to create a direct workflow task environment for reinforcement learning. We declared the scene in configuration and extended the base environment with actions, dones, reset, reward, and observation functions.
While it is possible to manually create an instance of DirectRLEnv class for a desired task,
this is not scalable as it requires specialized scripts for each task. Thus, we exploit the
gymnasium.make() function to create the environment with the gym interface. We will learn how to do this
in the next tutorial.