VLM Agent#
A vision-language model (VLM) can act as a policy without any robot training. At each request, Arena sends the model the task, the robot state, and the current camera images. The model returns a JSON command, and Arena checks it and executes it on the robot. The model is called through an OpenAI-compatible inference endpoint, so you do not need to run a model server.
The policies live in the isaaclab_arena_vlm_agent package. This guide runs them on the DROID
pick-and-place task, explains what each request contains, and shows how to connect your own robot
or execution strategy.
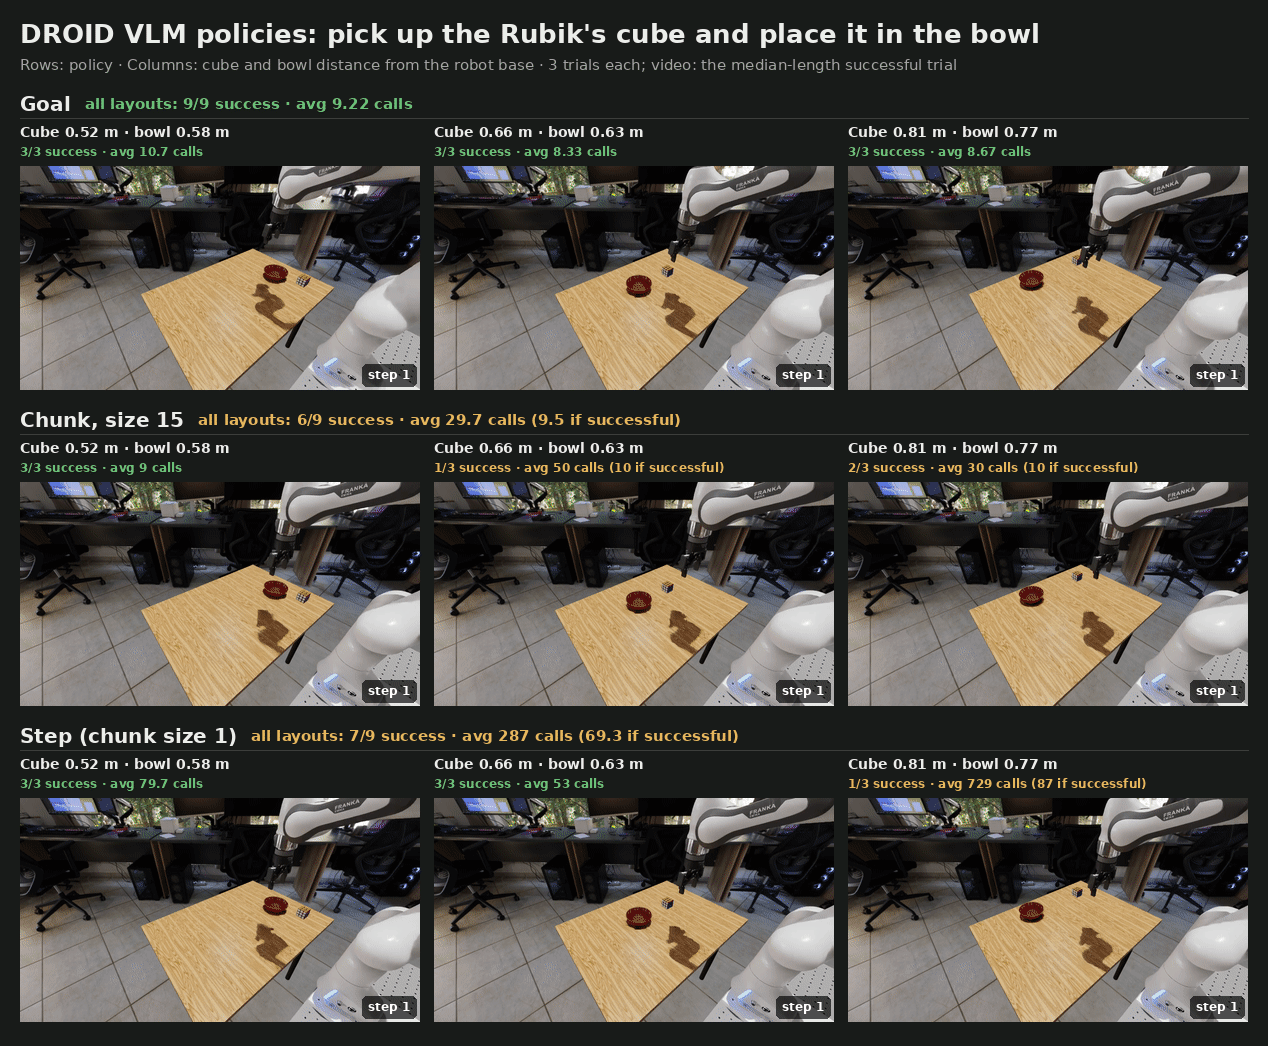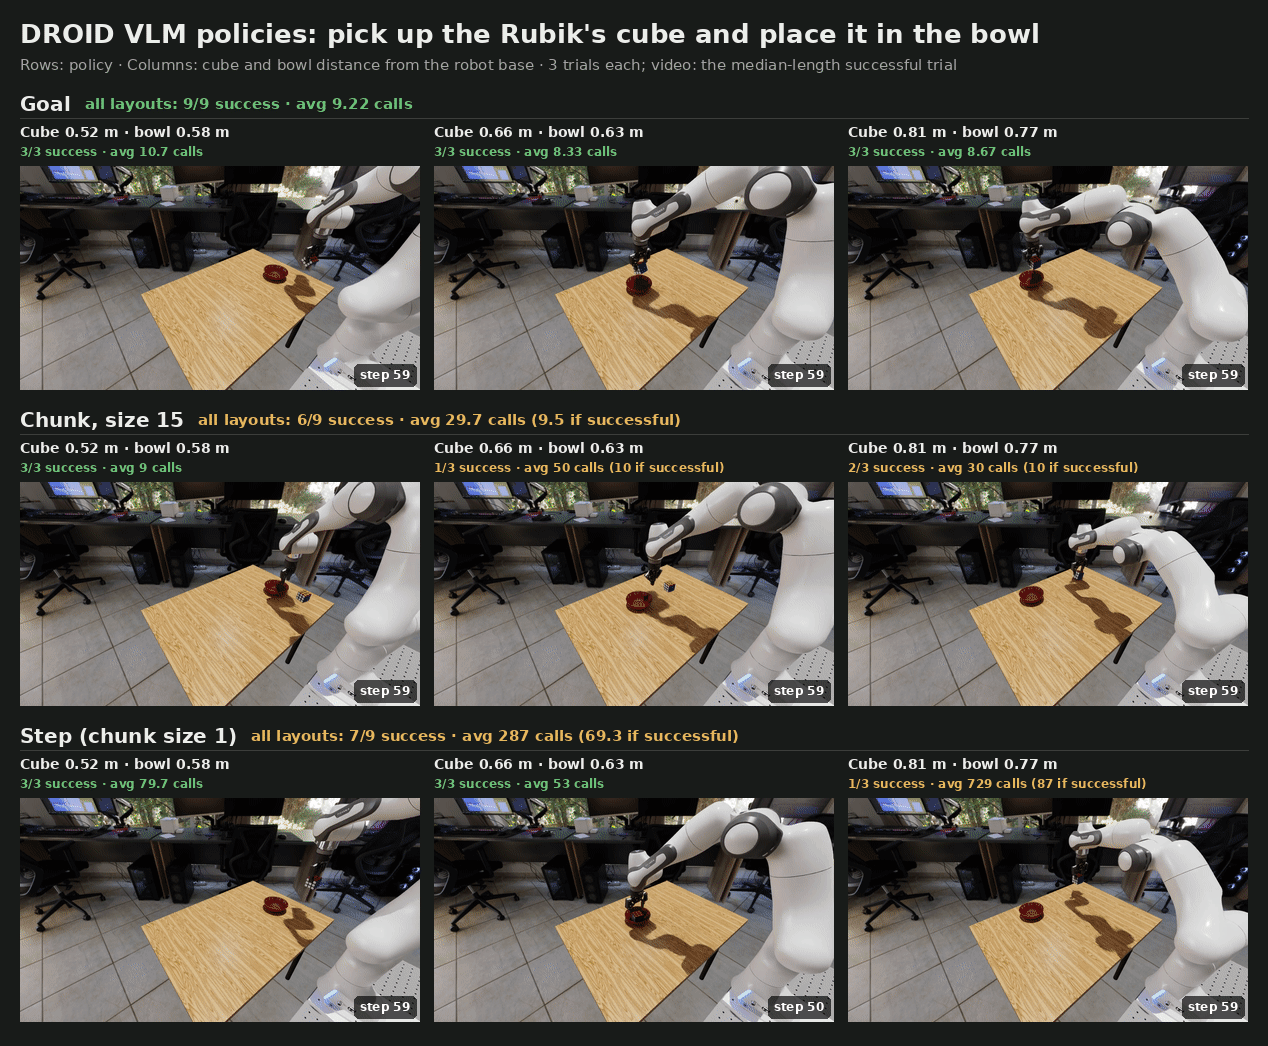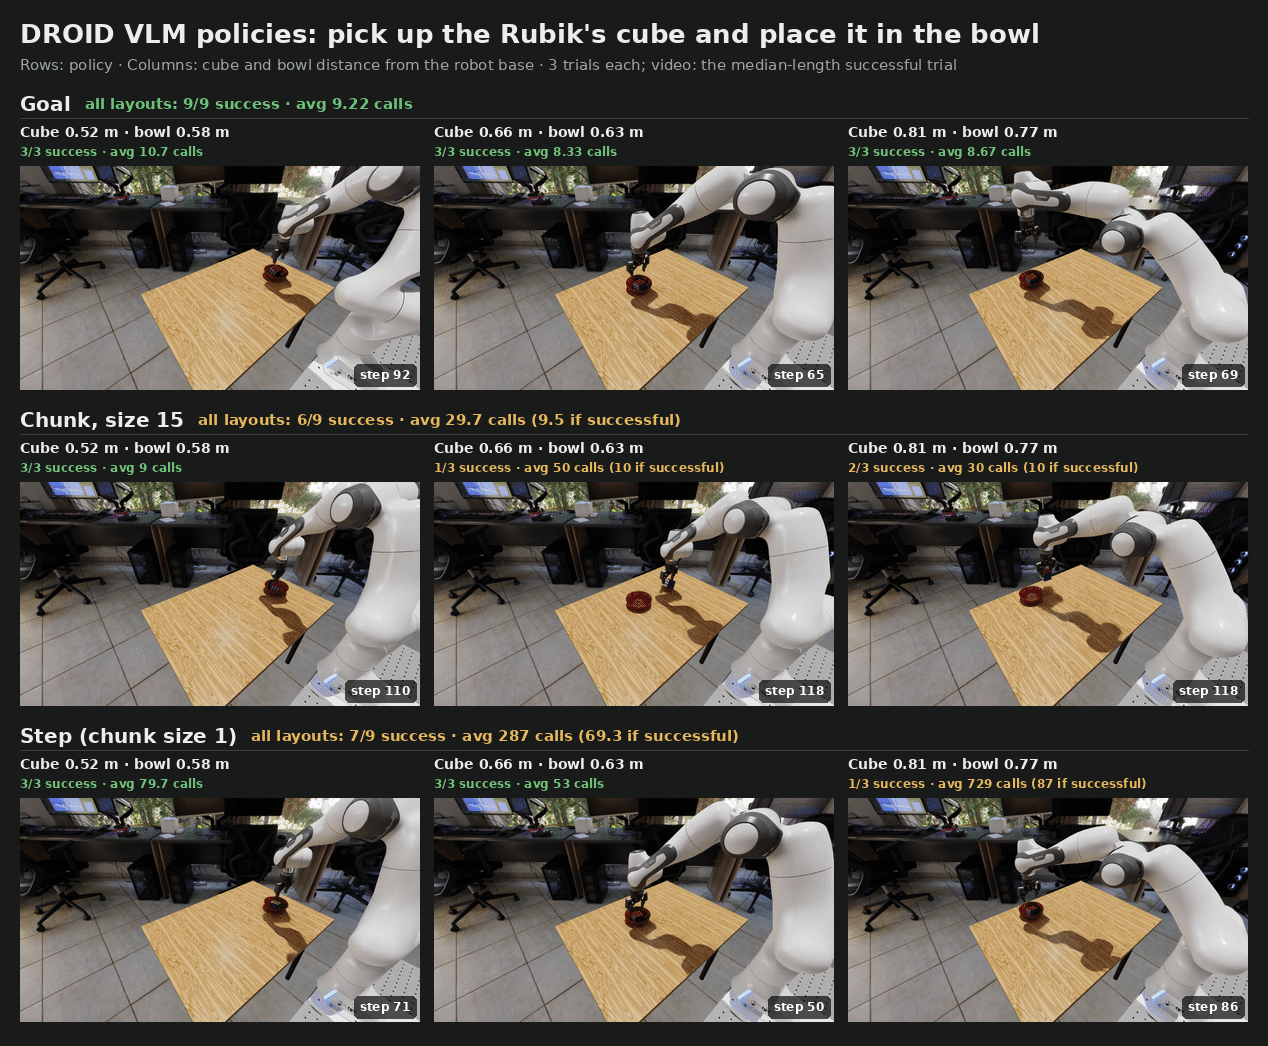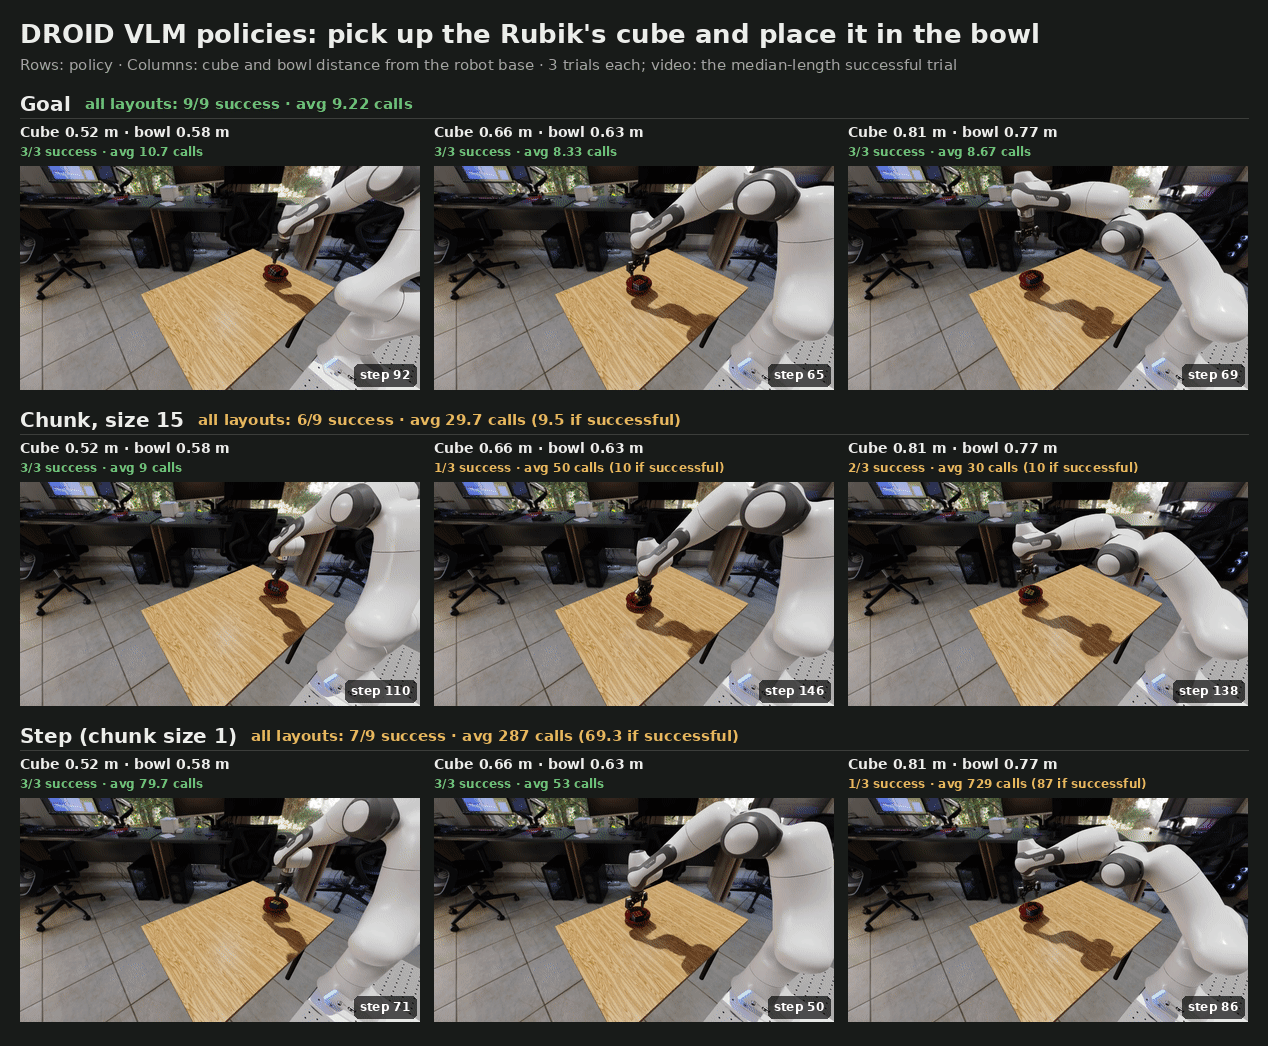
Three trials with openai/openai/gpt-6-astra for each execution strategy (rows) and layout
(columns, placement seeds 3, 2, and 19). Each layout is named by the cube and bowl distance from
the robot base. Captions give the successes and the average VLM calls per episode; each video
is one successful trial. The model is sampled, so trials of one layout can differ; see
Goal, chunk, and step policies.#
Prerequisites#
Inference API key setup#
The policy calls a remote VLM endpoint. Configure its API key before running an evaluation.
Export one or more API keys
in the host environment before launching a native uv runner or starting the
Docker container. Docker forwards the configured keys when it creates the
container. This step is required only once per host environment.
Generate an NGC API key at build.nvidia.com API keys, then export it for the publicly reachable endpoint:
export NVIDIA_API_KEY="YOUR_NGC_API_KEY"
Note
This endpoint is shared and is not always stable. A 504 Gateway Timeout
error usually means the service is overloaded or temporarily down. Wait a
few minutes, then retry the command.
From the NVIDIA network, generate an internal API key at inference.nvidia.com key management, then export it:
export NV_API_KEY="YOUR_INTERNAL_API_KEY"
Note
This endpoint is accessible by NVIDIA employees only and counts into your Inference Hub token usage.
Create an OpenAI account, generate a secret at OpenAI API keys, and configure payment or prepaid credits under OpenAI billing. OpenAI charges the account associated with the key according to its current API pricing and usage. Store the key securely and do not commit it to the repository.
export OPENAI_API_KEY="YOUR_OPENAI_API_KEY"
Note
The openai endpoint connects directly to a third-party service
operated by OpenAI, not NVIDIA. Its availability, regional
restrictions, data handling, pricing, and terms are controlled by
OpenAI. Review those terms before sending prompts or other data.
Select the endpoint and model#
Important
The model is the policy, so its capability sets the success rate. Use
openai/openai/gpt-6-astra, the model behind every result on this page, or a model of
similar capability. A smaller or weaker model may not complete the task at all.
Each Run selects its endpoint and model with policy.endpoint and policy.model in the
experiment configuration YAML:
runs:
  droid_pnp_vlm_goal:
    policy:
      type: isaaclab_arena_vlm_agent.vlm_agent_policy.VLMGoalPolicy
      endpoint: internal  # internal, public, or openai
      model: openai/openai/gpt-6-astra  # Must be served by the endpoint
      # base_url: <url>   # Optional: any OpenAI-compatible URL
|
API key variable |
Endpoint |
|---|---|---|
|
|
NVIDIA internal endpoint, for NVIDIA employees only. |
|
|
Public NVIDIA endpoint at build.nvidia.com. |
|
|
OpenAI API, billed to the OpenAI account that owns the key. |
policy.endpoint and policy.model are required and have no defaults, so a Run that leaves
either unset fails when the configuration loads. The example configurations set
endpoint: internal, which is accessible by NVIDIA employees only, and
model: openai/openai/gpt-6-astra, which only the internal endpoint serves. To switch one Run
without editing the YAML, override both fields on the command line with a model the endpoint
serves:
runs.droid_pnp_vlm_goal.policy.endpoint=internal  # internal, public, or openai
runs.droid_pnp_vlm_goal.policy.model=<model>
policy.base_url optionally sends the requests to any OpenAI-compatible URL instead. The API key
still comes from the endpoint’s variable.
The model must support strict JSON-schema structured outputs
(response_format={"type": "json_schema", ...}). With image observations, it must also accept
images. All results on this page were run with openai/openai/gpt-6-astra. When the policy
starts, it sends one short ping request, so a wrong key, URL, or model fails before the
simulation runs.
The pick-and-place task#
Both example configurations run one episode of pick_and_place_maple_table, the environment
from First Arena Environment: pick up the Rubik’s cube and place it in the bowl, in the
home_office_robolab scene. Two settings differ from that page:
Embodiment:
droid_abs_ikinstead ofdroid_rel_joint_pos. Each action is an absolute pose for the gripper’sbase_linkin the robot root frame, given as XYZ in meters followed by an XYZW quaternion, then a binary gripper command (0 opens, 1 closes). Differential IK tracks the pose.Task text: the
language_instructiontext is sent to the model as the task.
Run the example#
Important
This example evaluates how well an out-of-the-box VLM completes the task. The model is not trained or tuned for the robot, so task completion is not guaranteed. Success rates vary with the model and the placement seed, which sets the cube and bowl layout. They also vary between trials with the same seed, because the model’s responses are sampled, so the policy is not deterministic. Long pauses, grasp and placement mistakes, and failed episodes are expected results, not setup errors.
Prepare the Arena runtime from the repository root, using either a native uv environment or the
base Docker container (see Installation for the full setup):
uv sync --extra dev
source .venv/bin/activate
export OMNI_KIT_ACCEPT_EULA=YES ACCEPT_EULA=Y
./docker/run_docker.sh
Arena includes one configuration for each policy type:
Goal policy (droid_pnp_vlm_goal_experiment.yaml)
# Copyright (c) 2026, The Isaac Lab Arena Project Developers (https://github.com/isaac-sim/IsaacLab-Arena/blob/main/CONTRIBUTORS.md).
# All rights reserved.
#
# SPDX-License-Identifier: Apache-2.0

# Run inside the Arena runtime with NV_API_KEY set:
# /isaac-sim/python.sh isaaclab_arena/evaluation/experiment_runner.py --viz none \
#   --experiment_config isaaclab_arena_environments/experiment_configs/droid_pnp_vlm_goal_experiment.yaml
# Override endpoint/model/base_url as needed. Credentials stay in the environment.
# The droid preset supplies absolute-pose adapters, Robotiq measurements, and strategy-specific prompts.
# Set policy.system_prompt to override its default prompt.
runs:
  droid_pnp_vlm_goal:
    environment:
      type: pick_and_place_maple_table
      enable_cameras: true
      embodiment: droid_abs_ik
      pick_up_object: rubiks_cube_hot3d_robolab
      destination_location: bowl_ycb_robolab
      hdr: home_office_robolab
    environment_builder:
      num_envs: 1
      language_instruction: >-
        Pick up the Rubik's cube and place it in the bowl.
        Approach with the gripper open, close around the object, lift it,
        move above the destination, and open to release.
    policy:
      type: isaaclab_arena_vlm_agent.vlm_agent_policy.VLMGoalPolicy
      endpoint: internal  # internal, public, or openai
      # The model must be served by the endpoint.
      model: openai/openai/gpt-6-astra
      vlm_embodiment_adapter: droid
      observation_modality: image_state
      max_steps_per_goal: 30
    rollout_limit:
      num_episodes: 1
Chunk policy (droid_pnp_vlm_chunk_experiment.yaml)
# Copyright (c) 2026, The Isaac Lab Arena Project Developers (https://github.com/isaac-sim/IsaacLab-Arena/blob/main/CONTRIBUTORS.md).
# All rights reserved.
#
# SPDX-License-Identifier: Apache-2.0

# Run inside the Arena runtime with NV_API_KEY set:
# /isaac-sim/python.sh isaaclab_arena/evaluation/experiment_runner.py --viz none \
#   --experiment_config isaaclab_arena_environments/experiment_configs/droid_pnp_vlm_chunk_experiment.yaml
# Override endpoint/model/base_url as needed. Credentials stay in the environment.
# The droid preset supplies absolute-pose adapters, Robotiq measurements, and strategy-specific prompts.
# Set policy.system_prompt to override its default prompt.
runs:
  droid_pnp_vlm_chunk:
    environment:
      type: pick_and_place_maple_table
      enable_cameras: true
      embodiment: droid_abs_ik
      pick_up_object: rubiks_cube_hot3d_robolab
      destination_location: bowl_ycb_robolab
      hdr: home_office_robolab
    environment_builder:
      num_envs: 1
      language_instruction: >-
        Pick up the Rubik's cube and place it in the bowl.
        Approach with the gripper open, close around the object, lift it,
        move above the destination, and open to release.
    policy:
      type: isaaclab_arena_vlm_agent.vlm_agent_policy.VLMChunkPolicy
      endpoint: internal  # internal, public, or openai
      # The model must be served by the endpoint.
      model: openai/openai/gpt-6-astra
      vlm_embodiment_adapter: droid
      observation_modality: image_state
      chunk_size: 3
    rollout_limit:
      num_episodes: 1
Run the goal policy:
python isaaclab_arena/evaluation/experiment_runner.py \
  --viz kit \
  --experiment_config isaaclab_arena_environments/experiment_configs/droid_pnp_vlm_goal_experiment.yaml \
  runs.droid_pnp_vlm_goal.policy.endpoint=internal  # public or openai: also set policy.model
The runner prints the endpoint and model it connects to, then steps the episode. Run the chunk
policy the same way with droid_pnp_vlm_chunk_experiment.yaml.
The simulation is frozen while a request is in flight, and each request takes several seconds, so
the robot pauses every time the policy asks the model for a response. How often that happens
depends on the policy: the goal policy requests when a goal ends, the chunk policy every
chunk_size steps, and the step policy (chunk_size: 1) on every simulation step. The step
policy is therefore the slowest. A failed step episode makes a request on every step until the
episode ends, at the task’s time limit or earlier if the cube falls off the table. See
Goal, chunk, and step policies for the number of requests each policy makes.
Override settings for one Run on the command line. Each line below is one example:
# Step policy: one command per request
runs.droid_pnp_vlm_chunk.policy.chunk_size=1
# Longer chunks: fewer requests per episode
runs.droid_pnp_vlm_chunk.policy.chunk_size=15
# Another cube and bowl layout
runs.droid_pnp_vlm_chunk.environment_builder.placement_seed=2
# Four parallel environments, whose requests are sent concurrently
runs.droid_pnp_vlm_chunk.environment_builder.num_envs=4
# Another endpoint and model
runs.droid_pnp_vlm_goal.policy.endpoint=internal  # internal, public, or openai
runs.droid_pnp_vlm_goal.policy.model=<model>
For example, to run the step policy, which makes one request per simulation step:
python isaaclab_arena/evaluation/experiment_runner.py \
  --viz kit \
  --experiment_config isaaclab_arena_environments/experiment_configs/droid_pnp_vlm_chunk_experiment.yaml \
  runs.droid_pnp_vlm_chunk.policy.chunk_size=1 \
  runs.droid_pnp_vlm_chunk.policy.endpoint=internal  # public or openai: also set policy.model
Add --output_base_dir ./output --record_camera_video to save one video per camera, and add
--serve_evaluation_report to browse them, as for the OpenPI policy.
Goal, chunk, and step policies#
The two registered policies differ in what one response controls. The last three columns come from the trials in the figure: three per layout, nine per policy.
Policy |
One response contains |
Executed as |
Successes |
Requests per successful episode |
Tokens per successful episode |
|---|---|---|---|---|---|
|
One goal pose and gripper state |
A motion generator moves the arm toward the goal each step. The policy requests a new
goal when the current one is reached, blocked (the arm and gripper stopped short
of it), or timed out after |
9 of 9 |
8–12 (mean 9) |
19k–30k (mean 23k) |
|
15 commands |
One command per step. The policy requests the next chunk when the current one is used up. |
6 of 9 |
5–14 (mean 9.5) |
17k–47k (mean 32k) |
Step ( |
One command |
One request per simulation step. |
7 of 9 |
44–96 (mean 69) |
108k–227k (mean 167k) |
Every request sends about 2,000–2,200 prompt tokens, including three 384-pixel images. What the model returns differs by policy: about 300 tokens for a goal, 100 for a step command, and 1,400 for a chunk of 15 commands. Most of these are model reasoning. A step episode costs the most because it makes the most requests.
A failed episode costs far more than a successful one, because the policy keeps requesting until the episode ends, at 1,050 steps or earlier if the cube falls off the table. A failed chunk episode used about 240k tokens, and a failed step episode about 2.4M.
Step mode is also the most sensitive to a single bad response. A command executes on the very next step, so one stray “open” while the robot carries the cube drops it. Goal and long-chunk modes request far less often and give the model time to observe the result of each response.
Next steps#
To see what each request contains, and how to connect another robot or add an execution strategy, see Agent as Policy.