Evaluation in Arena#
Docker Container: Base (see Installation for more details)
./docker/run_docker.sh
Once inside the container, set the models directory:
export MODELS_DIR=/models/isaaclab_arena/dexsuite_lift
mkdir -p $MODELS_DIR
This step evaluates Isaac Lab’s published Newton state-policy checkpoint using
Arena’s dexsuite_lift environment. Arena uses the corresponding policy,
observation, command, control-rate, and physics configuration with its
procedural cube and pose-range reset.
Download Pre-trained Model (skip training)
/isaac-sim/python.sh - <<'PY'
import os
import shutil

from isaaclab_rl.utils.pretrained_checkpoint import get_published_pretrained_checkpoint

source = get_published_pretrained_checkpoint(
    "rsl_rl", "Isaac-Lift-KukaAllegro", "newtonmjwarp", "none"
)
assert source is not None
destination = os.path.join(os.environ["MODELS_DIR"], "Isaac-Lift-KukaAllegro.pt")
shutil.copy2(source, destination)
print(destination)
PY

mkdir -p "$MODELS_DIR/params"
cp isaaclab_arena_examples/policy/dexsuite_lift_agent.yaml \
  "$MODELS_DIR/params/agent.yaml"
After downloading, the checkpoint is at:
$MODELS_DIR/Isaac-Lift-KukaAllegro.pt
Published checkpoints do not include params/agent.yaml. The copy command
installs Arena’s checked-in snapshot of Isaac Lab’s state-policy runner
configuration where RslRlActionPolicy expects it.
Note
If you trained locally (see Policy Training (Isaac Lab)), your checkpoints are at:
logs/rsl_rl/lift_kuka_allegro/<timestamp>/model_<iter>.pt
Replace the checkpoint paths in the examples below accordingly.
Single Environment Evaluation#
PYOPENGL_PLATFORM=glx python isaaclab_arena/evaluation/policy_runner.py \
  --viz newton_gl \
  --policy_type rsl_rl \
  --num_episodes 20 \
  --checkpoint_path $MODELS_DIR/Isaac-Lift-KukaAllegro.pt \
  dexsuite_lift
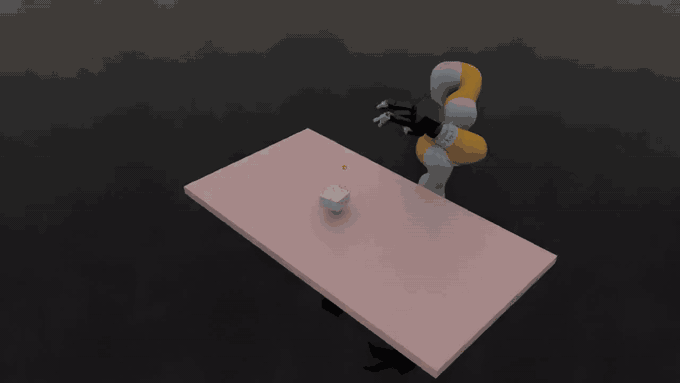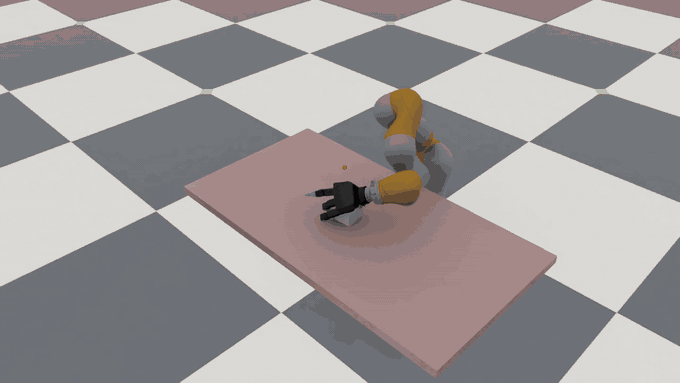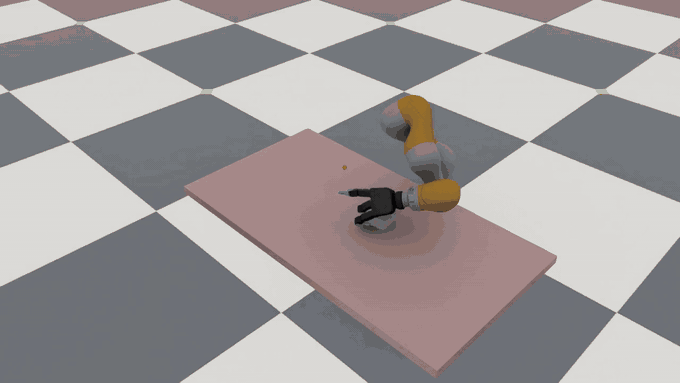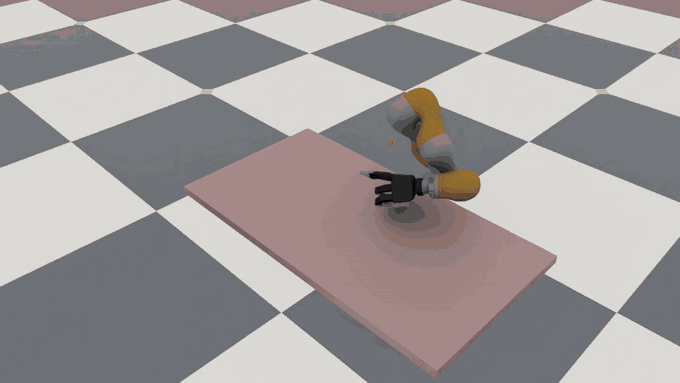
At the end of the run, metrics are printed to the console:
Metrics: {'num_episodes': 20, 'success_rate': 0.75}
Tip
You can also evaluate a Newton-trained model using PhysX:
python isaaclab_arena/evaluation/policy_runner.py \
  --viz kit \
  --presets physx \
  --policy_type rsl_rl \
  --num_steps 800 \
  --checkpoint_path $MODELS_DIR/Isaac-Lift-KukaAllegro.pt \
  dexsuite_lift
However, the model behaviour may differ significantly when training and evaluation use different physics backends; the published policy is validated against Newton.
Parallel Environment Evaluation#
For statistically significant results, run across many environments in parallel:
PYOPENGL_PLATFORM=glx python isaaclab_arena/evaluation/policy_runner.py \
  --viz newton_gl \
  --policy_type rsl_rl \
  --num_episodes 400 \
  --num_envs 64 \
  --env_spacing 3 \
  --checkpoint_path $MODELS_DIR/Isaac-Lift-KukaAllegro.pt \
  dexsuite_lift
Metrics: {'num_episodes': 400, 'success_rate': 0.82}
Batch Evaluation#
To evaluate multiple checkpoints in sequence, use experiment_runner.py with a
JSON config.
1. Create an evaluation config
Create a file eval_config.json:
{
  "jobs": [
    {
      "name": "dexsuite_lift_7500",
      "arena_env_args": {
        "environment": "dexsuite_lift",
        "num_envs": 64,
        "env_spacing": 3
      },
      "num_steps": 5000,
      "policy_type": "rsl_rl",
      "policy_config_dict": {
        "checkpoint_path": "models/isaaclab_arena/dexsuite_lift/model_7500.pt"
      }
    },
    {
      "name": "dexsuite_lift_14999",
      "arena_env_args": {
        "environment": "dexsuite_lift",
        "num_envs": 64,
        "env_spacing": 3
      },
      "num_steps": 5000,
      "policy_type": "rsl_rl",
      "policy_config_dict": {
        "checkpoint_path": "models/isaaclab_arena/dexsuite_lift/model_14999.pt"
      }
    }
  ]
}
2. Run
python isaaclab_arena/evaluation/experiment_runner.py --eval_jobs_config eval_config.json
Understanding the Metrics#
The dexsuite_lift task reports:
success_rate: fraction of episodes where the object reached the target position within 5 cm tolerance.num_episodes: total number of completed episodes.