

Registering an Environment#
In the previous tutorial, we learned how to create a custom cartpole environment. We manually
created an instance of the environment from the class named by its configuration’s class_type.
Environment creation in the previous tutorial
    # create environment configuration
    env_cfg = parse_env_cfg(
        "Isaac-Cartpole", device=args_cli.device, num_envs=args_cli.num_envs, overrides=hydra_overrides
    )
    # Launch the simulator runtime that the configuration needs
    with launch_simulation(env_cfg, args_cli):
        # setup RL environment
        env = instantiate(env_cfg)
While straightforward, this approach is not scalable as we have a large suite of environments.
In this tutorial, we will show how to use the gymnasium.register() method to register
environments with the gymnasium registry. This allows us to create the environment through
the gymnasium.make() function.
Environment creation in this tutorial
    env_cfg, _ = resolve_task_config(args_cli.task, "")
    apply_env_overrides(args_cli, env_cfg)
    # pass the resolved task device through to the launcher
    args_cli.device = env_cfg.sim.device
    # configure recorders before validation so invalid clip settings fail before the launch
    log_dir = os.path.abspath(os.path.join("logs", f"{policy}_agent", normalize_task_name(args_cli.task)))
    apply_video_recording(env_cfg, log_dir, args_cli, subdir="play")
    # reject unsupported configurations before launching Kit or initializing a native physics backend
    try:
        validate(env_cfg)
    except (TypeError, ValueError) as exc:
        raise SystemExit(f"Invalid environment configuration: {exc}") from None

    with launch_simulation(env_cfg, args_cli), contextlib.ExitStack() as cleanup:
        env = gym.make(args_cli.task, cfg=env_cfg)
The Code#
The tutorial corresponds to the random_agent.py script in the scripts/environments directory. The
script is a thin wrapper that calls into the isaaclab_rl.entrypoints module, where the actual
implementation lives.
Code for simple_agents.py
  1# Copyright (c) 2022-2026, The Isaac Lab Project Developers (https://github.com/isaac-sim/IsaacLab/blob/main/CONTRIBUTORS.md).
  2# All rights reserved.
  3#
  4# SPDX-License-Identifier: BSD-3-Clause
  5
  6"""Checkpoint-free playback workflows for Isaac Lab environments.
  7
  8The zero and random agents are variations of playback that need no trained checkpoint:
  9the policy either infers finite zero or hold actions or samples uniform random actions.
 10"""
 11
 12from __future__ import annotations
 13
 14import argparse
 15import contextlib
 16import os
 17import sys
 18from collections.abc import Callable
 19from typing import Any, Literal
 20
 21import gymnasium as gym
 22import torch
 23
 24from isaaclab.app import add_launcher_args, launch_simulation
 25from isaaclab.envs import DirectMARLEnvCfg
 26from isaaclab.envs.utils.spaces import sample_space
 27from isaaclab.utils import math as math_utils
 28from isaaclab.utils import validate
 29
 30import isaaclab_tasks  # noqa: F401
 31from isaaclab_tasks.utils import resolve_task_config, setup_preset_cli
 32
 33from .common import (
 34    add_video_args,
 35    apply_env_overrides,
 36    apply_video_recording,
 37    close_env,
 38    enable_cameras_for_video,
 39    normalize_task_name,
 40    video_playback_steps,
 41)
 42
 43# PLACEHOLDER: Extension template (do not remove this comment)
 44with contextlib.suppress(ImportError):
 45    import isaaclab_tasks_experimental  # noqa: F401
 46
 47PolicyName = Literal["zero", "random"]
 48"""Action policies supported by the checkpoint-free agents."""
 49
 50_DESCRIPTIONS: dict[str, str] = {
 51    "zero": "Zero agent for Isaac Lab environments.",
 52    "random": "Random agent for Isaac Lab environments.",
 53}
 54
 55_SEED = 42
 56
 57
 58def run(argv: list[str] | None = None, *, policy: PolicyName) -> None:
 59    """Run an Isaac Lab environment with a checkpoint-free policy.
 60
 61    Args:
 62        argv: Command-line arguments excluding the executable name. Reads ``sys.argv`` when omitted.
 63        policy: Action policy to apply, either inferred zero actions or uniform random actions.
 64
 65    Raises:
 66        ValueError: If the requested policy is not supported.
 67    """
 68    if policy not in _DESCRIPTIONS:
 69        raise ValueError(f"Unsupported policy {policy!r}. Expected one of: {sorted(_DESCRIPTIONS)}.")
 70
 71    args_cli = _parse_args(argv, policy)
 72    torch.manual_seed(_SEED)
 73
 74    env_cfg, _ = resolve_task_config(args_cli.task, "")
 75    apply_env_overrides(args_cli, env_cfg)
 76    # pass the resolved task device through to the launcher
 77    args_cli.device = env_cfg.sim.device
 78    # configure recorders before validation so invalid clip settings fail before the launch
 79    log_dir = os.path.abspath(os.path.join("logs", f"{policy}_agent", normalize_task_name(args_cli.task)))
 80    apply_video_recording(env_cfg, log_dir, args_cli, subdir="play")
 81    # reject unsupported configurations before launching Kit or initializing a native physics backend
 82    try:
 83        validate(env_cfg)
 84    except (TypeError, ValueError) as exc:
 85        raise SystemExit(f"Invalid environment configuration: {exc}") from None
 86
 87    with launch_simulation(env_cfg, args_cli), contextlib.ExitStack() as cleanup:
 88        env = gym.make(args_cli.task, cfg=env_cfg)
 89        cleanup.callback(lambda: close_env(env))
 90        print(f"[INFO]: Gym observation space: {env.observation_space}")
 91        print(f"[INFO]: Gym action space: {env.action_space}")
 92        env.reset()
 93        if policy == "zero":
 94            action_policy = create_zero_action_policy(env)
 95        else:
 96            action_policy = create_random_action_policy(env)
 97        print(f"[INFO] {policy.capitalize()} agent is running, press Ctrl+C to exit...")
 98
 99        budgets = [n for n in (args_cli.max_steps, video_playback_steps(args_cli, env_cfg)) if n is not None]
100        max_steps = min(budgets, default=None)
101
102        # keep running while any visualizer is open and the step budget is not exhausted
103        sim = env.unwrapped.sim
104        step = 0
105        while sim.is_running():
106            if max_steps is not None and step >= max_steps:
107                break
108            step += 1
109            with torch.inference_mode():
110                env.step(action_policy())
111
112
113def create_zero_action_policy(env: gym.Env) -> Callable[[], Any]:
114    """Create a policy that emits finite actions for passive environment playback.
115
116    Manager-based environments infer hold commands for absolute task-space action terms and use literal zeros for all
117    other terms. Direct-workflow environments use zero-filled samples of their declared Gymnasium spaces, including
118    composite and multi-agent spaces.
119    """
120    unwrapped = env.unwrapped
121    action_manager = getattr(unwrapped, "action_manager", None)
122    if action_manager is not None:
123        return _create_manager_zero_action_policy(action_manager, unwrapped)
124
125    if isinstance(unwrapped.cfg, DirectMARLEnvCfg):
126        actions = {
127            agent: sample_space(space, unwrapped.device, batch_size=unwrapped.num_envs, fill_value=0)
128            for agent, space in unwrapped.action_spaces.items()
129        }
130        return lambda: actions
131
132    actions = sample_space(unwrapped.single_action_space, unwrapped.device, batch_size=unwrapped.num_envs, fill_value=0)
133    return lambda: actions
134
135
136def create_random_action_policy(env: gym.Env) -> Callable[[], torch.Tensor | dict[str, torch.Tensor]]:
137    """Create a policy that samples uniform random actions in ``[-1, 1]`` for each environment and agent."""
138    unwrapped = env.unwrapped
139    device = unwrapped.device
140    if isinstance(unwrapped.cfg, DirectMARLEnvCfg):
141        return lambda: {
142            agent: 2 * torch.rand((unwrapped.num_envs, *space.shape), device=device) - 1
143            for agent, space in unwrapped.action_spaces.items()
144        }
145
146    return lambda: 2 * torch.rand(env.action_space.shape, device=device) - 1
147
148
149def _create_manager_zero_action_policy(action_manager: Any, env: Any) -> Callable[[], torch.Tensor]:
150    """Create a zero-action policy from the active action terms."""
151    actions = torch.zeros_like(action_manager.action)
152    term_policies = []
153    index = 0
154    for term_name in action_manager.active_terms:
155        term = action_manager.get_term(term_name)
156        term_policy = _create_action_term_zero_policy(term, env)
157        if term_policy is not None:
158            term_policies.append((slice(index, index + term.action_dim), term_policy))
159        index += term.action_dim
160
161    def policy() -> torch.Tensor:
162        actions.zero_()
163        for action_slice, term_policy in term_policies:
164            actions[:, action_slice] = term_policy()
165        if not torch.isfinite(actions).all():
166            raise RuntimeError("Zero agent inferred non-finite actions from the current environment state.")
167        return actions
168
169    return policy
170
171
172def _create_action_term_zero_policy(term: Any, env: Any) -> Callable[[], torch.Tensor] | None:
173    """Create the specialized zero-action policy required by an action term."""
174    term_types = {cls.__name__ for cls in type(term).__mro__}
175
176    if "PinkInverseKinematicsAction" in term_types:
177        controlled_frame_ids, controlled_frame_names = term._asset.find_bodies(
178            list(term.cfg.target_eef_link_names.values()), preserve_order=True
179        )
180        if len(controlled_frame_ids) != len(term.cfg.target_eef_link_names):
181            raise ValueError(
182                "Expected one controlled body for every Pink IK target. Resolved "
183                f"{controlled_frame_names} from {list(term.cfg.target_eef_link_names.values())}."
184            )
185        if len(controlled_frame_ids) != term._num_frame_tasks:
186            raise ValueError(
187                f"Pink IK has {term._num_frame_tasks} variable frame tasks but "
188                f"{len(controlled_frame_ids)} controlled bodies were configured."
189            )
190
191        def pink_policy() -> torch.Tensor:
192            frame_poses = term._asset.data.body_link_pose_w.torch[:, controlled_frame_ids].clone()
193            frame_poses[..., :3] -= env.scene.env_origins.unsqueeze(1)
194            hand_joint_positions = term._asset.data.joint_pos.torch[:, term._hand_joint_ids]
195            return torch.cat((frame_poses.flatten(start_dim=1), hand_joint_positions), dim=-1)
196
197        return pink_policy
198
199    if "DifferentialInverseKinematicsAction" in term_types and not term.cfg.controller.use_relative_mode:
200
201        def differential_ik_policy() -> torch.Tensor:
202            ee_pos, ee_quat = term._compute_frame_pose()
203            command = ee_pos if term.cfg.controller.command_type == "position" else torch.cat((ee_pos, ee_quat), dim=-1)
204            return _unscale_action(command - term._offset, term._scale)
205
206        return differential_ik_policy
207
208    if "RMPFlowAction" in term_types and not term.cfg.use_relative_mode:
209
210        def rmpflow_policy() -> torch.Tensor:
211            ee_pos, ee_quat = term._compute_frame_pose()
212            return _unscale_action(torch.cat((ee_pos, ee_quat), dim=-1), term._scale)
213
214        return rmpflow_policy
215
216    if "OperationalSpaceControllerAction" in term_types and term._pose_abs_idx is not None:
217        term_actions = torch.zeros_like(term.raw_actions)
218
219        def operational_space_policy() -> torch.Tensor:
220            term_actions.zero_()
221            term._compute_ee_pose()
222            term._compute_task_frame_pose()
223            if term._task_frame_pose_b is None:
224                ee_pos_task = term._ee_pose_b[:, :3]
225                ee_quat_task = term._ee_pose_b[:, 3:7]
226            else:
227                ee_pos_task, ee_quat_task = math_utils.subtract_frame_transforms(
228                    term._task_frame_pose_b[:, :3],
229                    term._task_frame_pose_b[:, 3:7],
230                    term._ee_pose_b[:, :3],
231                    term._ee_pose_b[:, 3:7],
232                )
233            term_actions[:, term._pose_abs_idx : term._pose_abs_idx + 3] = _unscale_action(
234                ee_pos_task, term._position_scale
235            )
236            term_actions[:, term._pose_abs_idx + 3 : term._pose_abs_idx + 7] = _unscale_action(
237                ee_quat_task, term._orientation_scale
238            )
239            return term_actions
240
241        return operational_space_policy
242
243    return None
244
245
246def _unscale_action(command: torch.Tensor, scale: torch.Tensor) -> torch.Tensor:
247    """Map a processed command back to policy-action coordinates without division by zero."""
248    return torch.where(scale != 0.0, command / scale, torch.zeros_like(command))
249
250
251def _parse_args(argv: list[str] | None, policy: PolicyName) -> argparse.Namespace:
252    """Parse the command line of a checkpoint-free agent and hand the remainder to Hydra."""
253    parser = argparse.ArgumentParser(description=_DESCRIPTIONS[policy])
254    parser.add_argument(
255        "--disable_fabric", action="store_true", default=False, help="Disable fabric and use USD I/O operations."
256    )
257    parser.add_argument("--num_envs", type=int, default=None, help="Number of environments to simulate.")
258    parser.add_argument("--task", type=str, default=None, help="Name of the task.")
259    parser.add_argument(
260        "--max_steps", type=int, default=None, help="Number of environment steps to run. Runs unbounded when omitted."
261    )
262    add_video_args(parser, action=f"the {policy} agent run")
263    add_launcher_args(parser)
264    # let task configs select the simulation device and keep checkpoint-free agents on the kitless default path
265    parser.set_defaults(device=None, visualizer=["newton_gl"])
266    args_cli, hydra_args = setup_preset_cli(parser, argv)
267    enable_cameras_for_video(args_cli)
268    sys.argv = [sys.argv[0]] + hydra_args
269    return args_cli
The Code Explained#
The envs.ManagerBasedRLEnv class inherits from the gymnasium.Env class to follow
a standard interface. However, unlike the traditional Gym environments, the envs.ManagerBasedRLEnv
implements a vectorized environment. This means that multiple environment instances
are running simultaneously in the same process, and all the data is returned in a batched
fashion.
Similarly, the envs.DirectRLEnv class also inherits from the gymnasium.Env class
for the direct workflow. For envs.DirectMARLEnv, although it does not inherit
from Gymnasium, it can be registered and created in the same way.
Using the gym registry#
To register an environment, we use the gymnasium.register() method. This method takes
in the environment name, the entry point to the environment class, and the entry point to the
environment configuration class.
Note
The gymnasium registry is a global registry. Hence, it is important to ensure that the
environment names are unique. Otherwise, the registry will throw an error when registering
the environment.
Manager-Based Environments#
For manager-based environments, the following shows the registration
call for the cartpole environment in the isaaclab_tasks.core.cartpole sub-package:
from . import agents

        "rsl_rl_cfg_entry_point": f"{agents.__name__}.rsl_rl_ppo_cfg:CartpolePPORunnerCfg",
        "torchrl_cfg_entry_point": f"{agents.__name__}.torchrl_ppo_cfg:CartpolePPOCfg",
        "default_agent": "rsl_rl",
        "rsl_rl_with_symmetry_cfg_entry_point": (
            f"{agents.__name__}.rsl_rl_ppo_cfg:CartpolePPORunnerWithSymmetryCfg"
        ),
        "skrl_cfg_entry_point": f"{agents.__name__}:skrl_manager_ppo_cfg.yaml",
        "sb3_cfg_entry_point": f"{agents.__name__}:sb3_ppo_cfg.yaml",
    },
)

gym.register(
    id="Isaac-Cartpole-Camera",
    entry_point="isaaclab.envs:ManagerBasedRLEnv",
    disable_env_checker=True,
The id argument is the name of the environment. As a convention, we name all the environments
with the prefix Isaac- to make it easier to search for them in the registry. The name of the
environment is typically followed by the name of the task, and then the name of the robot.
For instance, for legged locomotion with ANYmal C on flat terrain, the environment is called
IsaacContrib-Velocity-Flat-AnymalC. The version number v<N> is typically used to specify different
variations of the same environment. Otherwise, the names of the environments can become too long
and difficult to read.
The entry_point argument is the entry point to the environment class. The entry point is a string
of the form <module>:<class>. In the case of the cartpole environment, the entry point is
isaaclab.envs:ManagerBasedRLEnv. The entry point is used to import the environment class
when creating the environment instance.
The env_cfg_entry_point argument specifies the default configuration for the environment. The default
configuration is loaded using the isaaclab_tasks.utils.parse_env_cfg() function.
It is then passed to the gymnasium.make() function to create the environment instance.
The configuration entry point can be both a YAML file or a python configuration class.
Direct Environments#
For direct-based environments, the environment registration follows a similar pattern. Instead of
registering the environment’s entry point as the ManagerBasedRLEnv class,
we register the environment’s entry point as the implementation class of the environment.
Additionally, we add the suffix -Direct to the environment name to differentiate it from the
manager-based environments.
As an example, the following shows the registration call for the cartpole environment in the
isaaclab_tasks.core.cartpole sub-package:
from . import agents

        "sb3_cfg_entry_point": f"{agents.__name__}:sb3_ppo_cfg.yaml",
    },
)

gym.register(
    id="Isaac-Cartpole-Camera-Direct",
    entry_point=f"{__name__}.cartpole_direct_camera_env:CartpoleCameraEnv",
    disable_env_checker=True,
    kwargs={
        "env_cfg_entry_point": f"{__name__}.cartpole_direct_camera_env_cfg:CartpoleCameraEnvCfg",
        "rl_games_cfg_entry_point": f"{agents.__name__}:rl_games_camera_ppo_cfg.yaml",
        "rsl_rl_cfg_entry_point": f"{agents.__name__}.rsl_rl_ppo_cfg:CartpoleCameraDirectPPORunnerCfg",
Creating the environment#
To inform the gym registry with all the environments provided by the isaaclab_tasks
extension, we must import the module at the start of the script. This will execute the __init__.py
file which iterates over all the sub-packages and registers their respective environments.
import isaaclab_tasks # noqa: F401
In this tutorial, the task name is read from the command line. The task name is used to parse the default configuration as well as to create the environment instance. In addition, other parsed command line arguments such as the number of environments, the simulation device, and whether to render, are used to override the default configuration.
    env_cfg, _ = resolve_task_config(args_cli.task, "")
    apply_env_overrides(args_cli, env_cfg)
    # pass the resolved task device through to the launcher
    args_cli.device = env_cfg.sim.device
    # configure recorders before validation so invalid clip settings fail before the launch
    log_dir = os.path.abspath(os.path.join("logs", f"{policy}_agent", normalize_task_name(args_cli.task)))
    apply_video_recording(env_cfg, log_dir, args_cli, subdir="play")
    # reject unsupported configurations before launching Kit or initializing a native physics backend
    try:
        validate(env_cfg)
    except (TypeError, ValueError) as exc:
        raise SystemExit(f"Invalid environment configuration: {exc}") from None

    with launch_simulation(env_cfg, args_cli), contextlib.ExitStack() as cleanup:
        env = gym.make(args_cli.task, cfg=env_cfg)
Once creating the environment, the rest of the execution follows the standard resetting and stepping.
The Code Execution#
Now that we have gone through the code, let’s run the script and see the result:
uv run python scripts/environments/random_agent.py --task Isaac-Cartpole --num_envs 32 --viz kit
./isaaclab.sh -p scripts/environments/random_agent.py --task Isaac-Cartpole --num_envs 32 --viz kit
This should open a stage with everything similar to the Creating a Manager-Based RL Environment tutorial.
To stop the simulation, you can either close the window, or press Ctrl+C in the terminal.
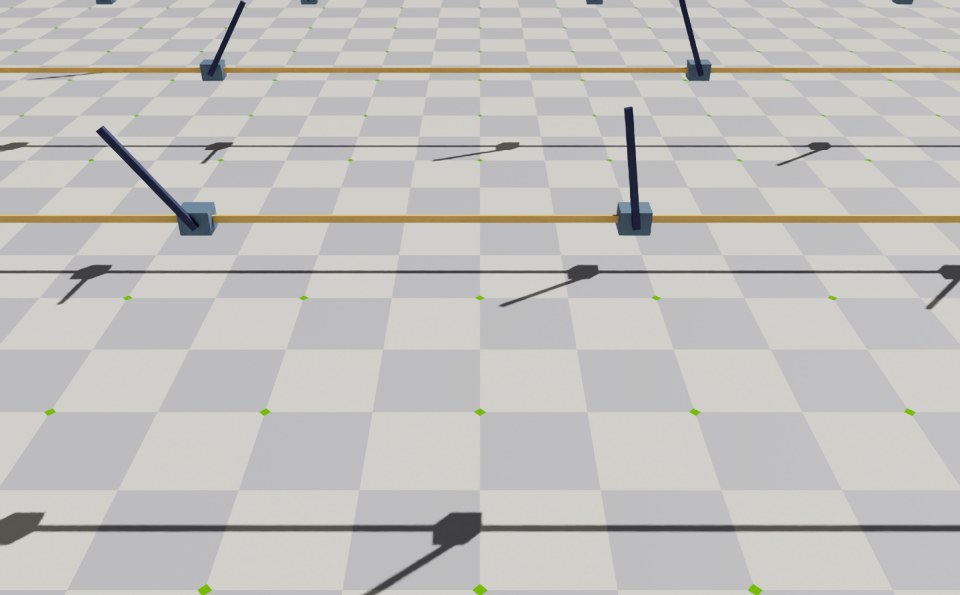
In addition, you can also change the simulation device from GPU to CPU by setting the value of the --device flag explicitly:
uv run python scripts/environments/random_agent.py --task Isaac-Cartpole --num_envs 32 --device cpu --viz kit
./isaaclab.sh -p scripts/environments/random_agent.py --task Isaac-Cartpole --num_envs 32 --device cpu --viz kit
With the --device cpu flag, the simulation will run on the CPU. This is useful for debugging the simulation.
However, the simulation will run much slower than on the GPU.